00

I engineer signal and tell the story.

Data Analyst, Data Scientist, Data Engineer, AI Engineer, AI / ML Engineer, Analytics Engineer

Pipelines, dashboards, models, and the retrieval and APIs that serve them. I build the whole path from raw data to a working system.

B.S. Computer Science · Data Science
Arizona State University, 2026

Scroll
Drag the helix
Pavan Venkata Manjunath Mallipudi Pavan Mallipudi · Tempe, AZ

One instinct across the whole stack: take the noise, find the signal, and put it to work.

I work end to end: the pipelines that move the data, the models and retrieval that reason over it, and the dashboards and APIs that put it in front of people. The part I care about most is the handoff, where a number becomes a decision or a model becomes something you can actually call.

FocusAnalytics · Data Engineering · AI / ML
BasedTempe, AZ · Open to relocation
StatusOpen to roles
Work authApproved OPT · 3-yr STEM
StackPython · SQL · Spark · PyTorch · BI
CertifiedAWS AI & Cloud Practitioner
3.76 /4.0
GPA · Dean's List
8
Projects shipped
2 yrs
Experience
20+
Technologies

Areas of interest

Data AnalyticsBusiness IntelligenceData EngineeringData VisualizationStatistical AnalysisMachine LearningDeep LearningComputer VisionAI / LLMsCloud & Big DataMLOps

Education

Academic background
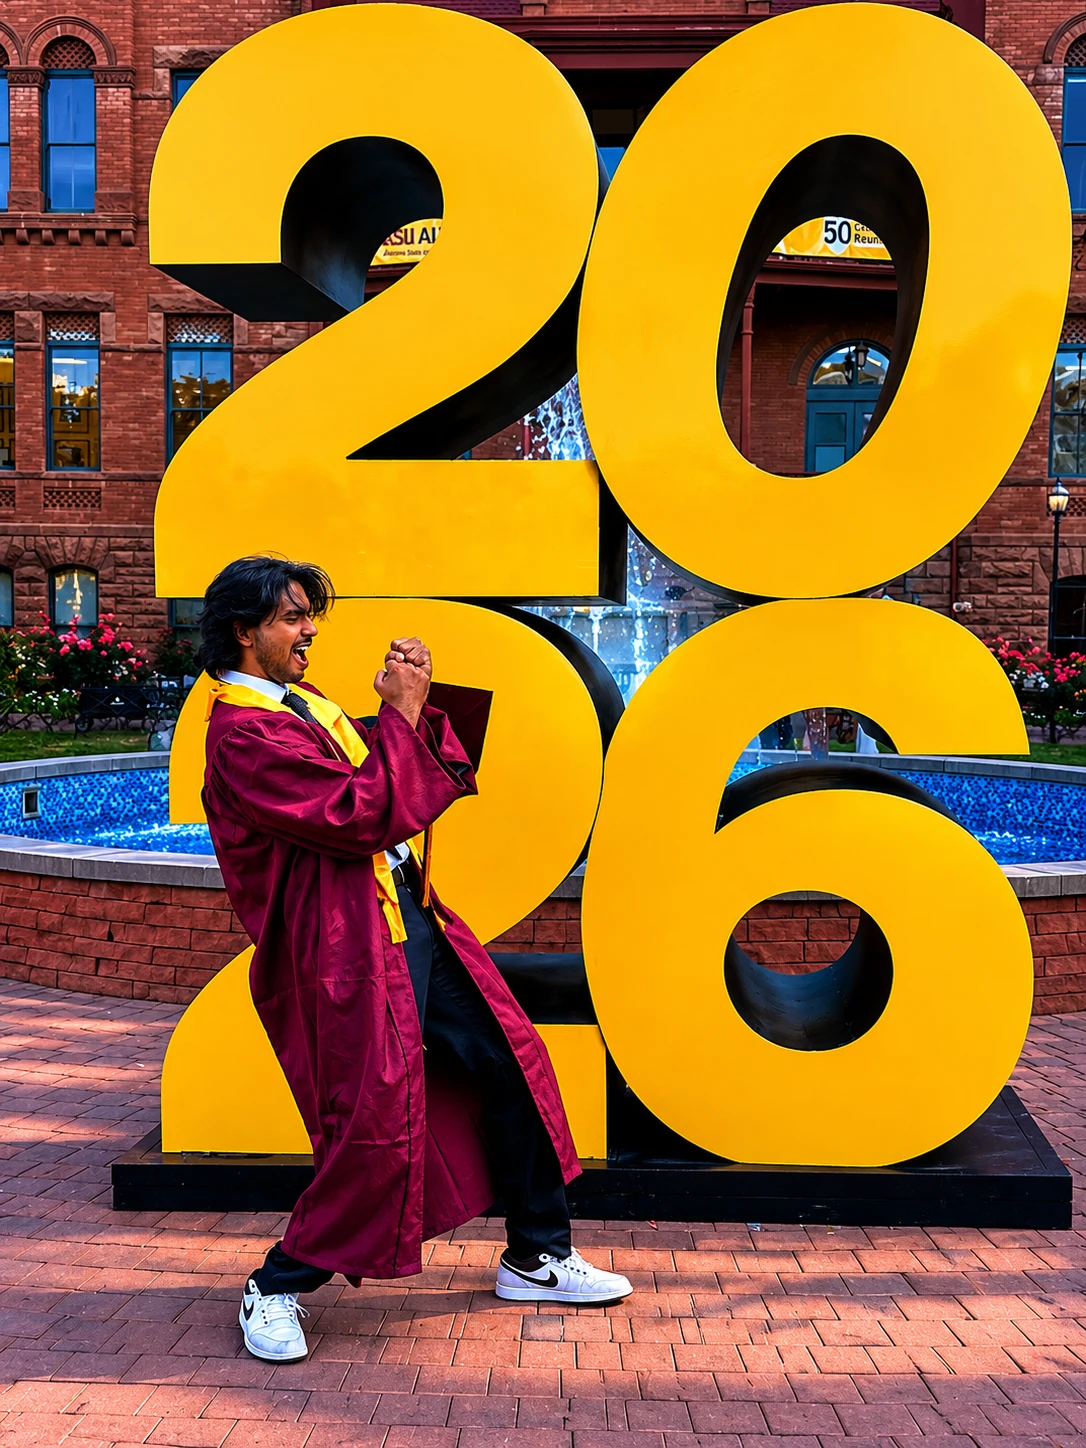
Pavan in cap and gown celebrating at the ASU Class of 2026 sign
Commencement, May 2026 · Class of 2026

Arizona State University

B.S. Computer Science · Minor in Data Science · Magna Cum Laude

Tempe, AZ · Aug 2022 - May 2026 (Graduated)
3.76 / 4.0GPA · 5× Dean's List

Honors

Magna Cum LaudeDean's List, 5 semesters

Relevant coursework

Data Structures & AlgorithmsDatabase ManagementFoundations of Machine LearningApplied Linear AlgebraProbability & StatisticsStatistical Modeling & InferenceData in R & PythonData VisualizationObject Oriented Programming

Experience

Work history

Community Engagement Data Analyst

ASU Social Embeddedness · Office of University Affairs · Tempe, AZ
Sep 2024 - May 2026
  • Administered and validated 2,300+ community-engagement activities across 32 ASU units and 650 community organizations, implementing standardization and validation rules that increased required-field completeness from 78% to 96%.
  • Built Tableau Prep pipelines processing 30,000+ activity-unit-partner rows and developed 6 interactive dashboards tracking 10 institutional KPIs, used across 32 ASU units, reducing monthly reporting prep from 4 days to 6 hours.
  • Built a Python and GPT-4o mini workflow using structured JSON outputs to classify 900+ stakeholder narratives into 12 standardized themes, achieving 91% agreement with human-reviewed classifications and cutting review time from 8 to 3 minutes per record.
  • Delivered 24 platform demonstrations and support sessions to 70+ faculty and staff across 18 departments, contributing to a 28% increase in active platform contributors and a 35% reduction in recurring data-entry errors.
TableauTableau PrepPythonGPT-4o miniData Governance
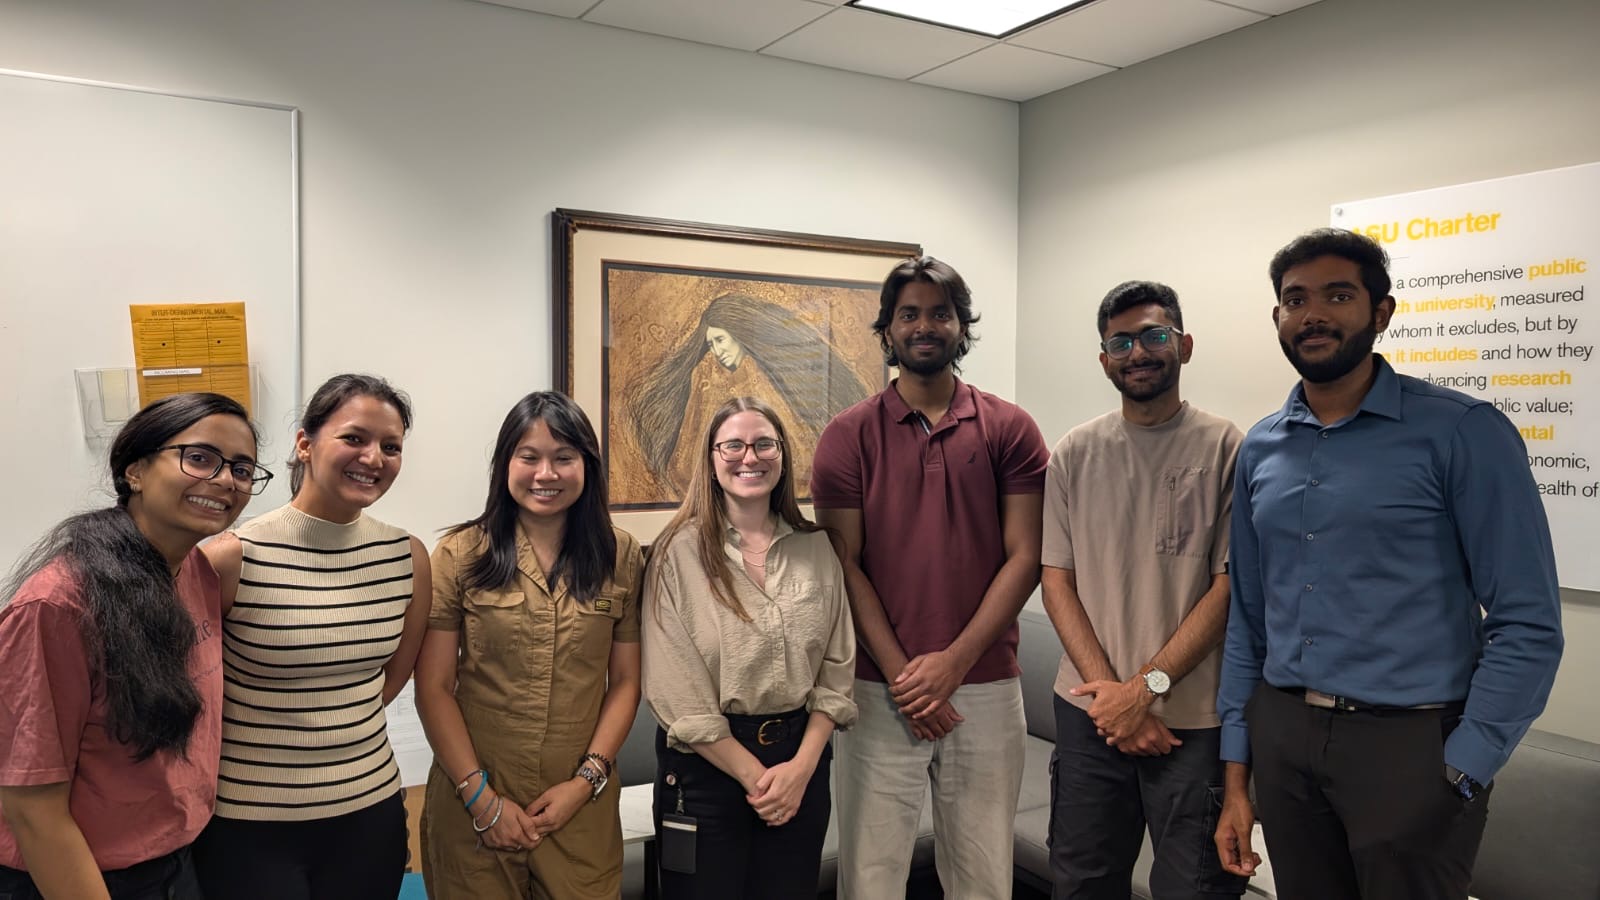
The Social Embeddedness team at ASU’s Office of University Affairs
Social Embeddedness team · ASU Office of University Affairs

Data Engineer

DigiClips (Capstone) · Lafayette, CO · Remote
Aug 2025 - Apr 2026
  • Automated nightly retention cleanup using MySQL Event Scheduler, purging ~20,000 expired metadata records monthly and cutting manual maintenance from 3 hours to 30 minutes per week.
  • Built data-quality routines across 12 MySQL tables, removing 4,500 duplicate records and correcting 2,000 timestamp inconsistencies, with automated weekly database dumps for backup and retention compliance.
  • Refactored 3 search stored procedures after reverse-engineering the relational schema, cutting median query latency 64% (1.8s → 650ms) on a 500K-record test database.
MySQLStored ProceduresETLData Quality
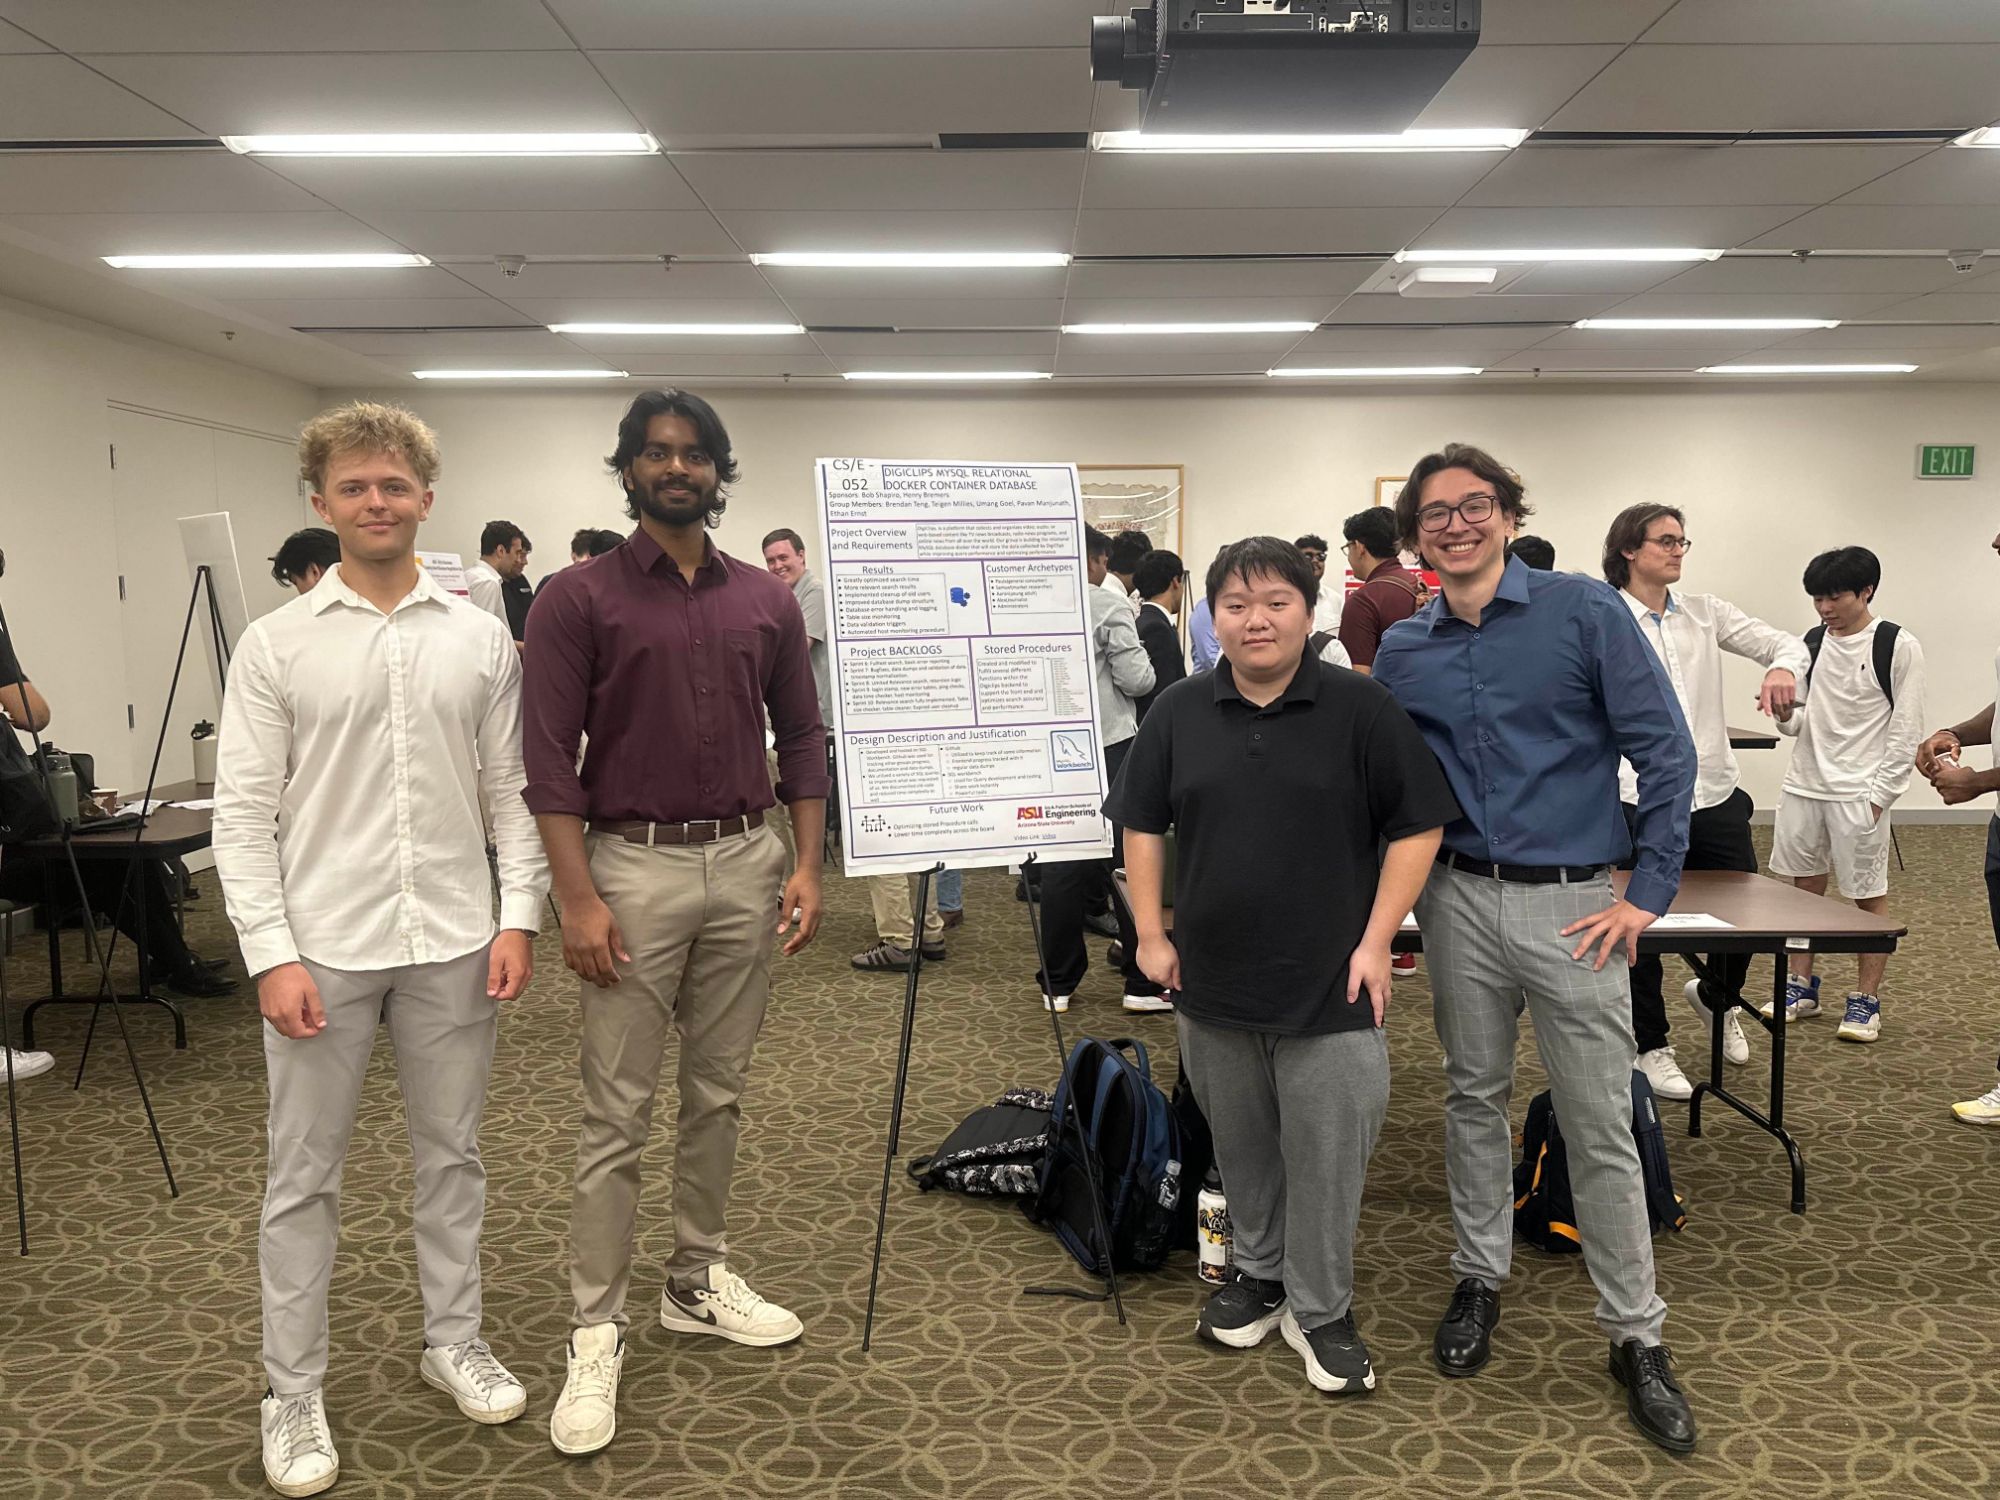
Presenting the DigiClips MySQL database poster at the ASU capstone showcase
Capstone showcase · DigiClips MySQL database

Data Analyst

Food Forest AI · Philadelphia, PA · Remote
Jun 2025 - Jul 2025
  • Built a document-ingestion pipeline converting 650+ supplier PDFs into standardized JSON profiles across 15 attributes, including extrusion capabilities, hot/cold-fill processing, facility locations, and SQF/Organic certifications.
  • Normalized 40+ variations in processing capabilities and certification naming through data-cleaning logic, reducing average supplier onboarding time from 12 to 4 minutes.
  • Built Python/SQL data-quality checks across 2,500+ supplier profiles (420 missing fields, 275 formatting anomalies, 110 duplicates found) and Power BI dashboards tracking 8,000+ B2B search events across 5 pilot clients to support product decisions.
PythonGenAISQLPower BI
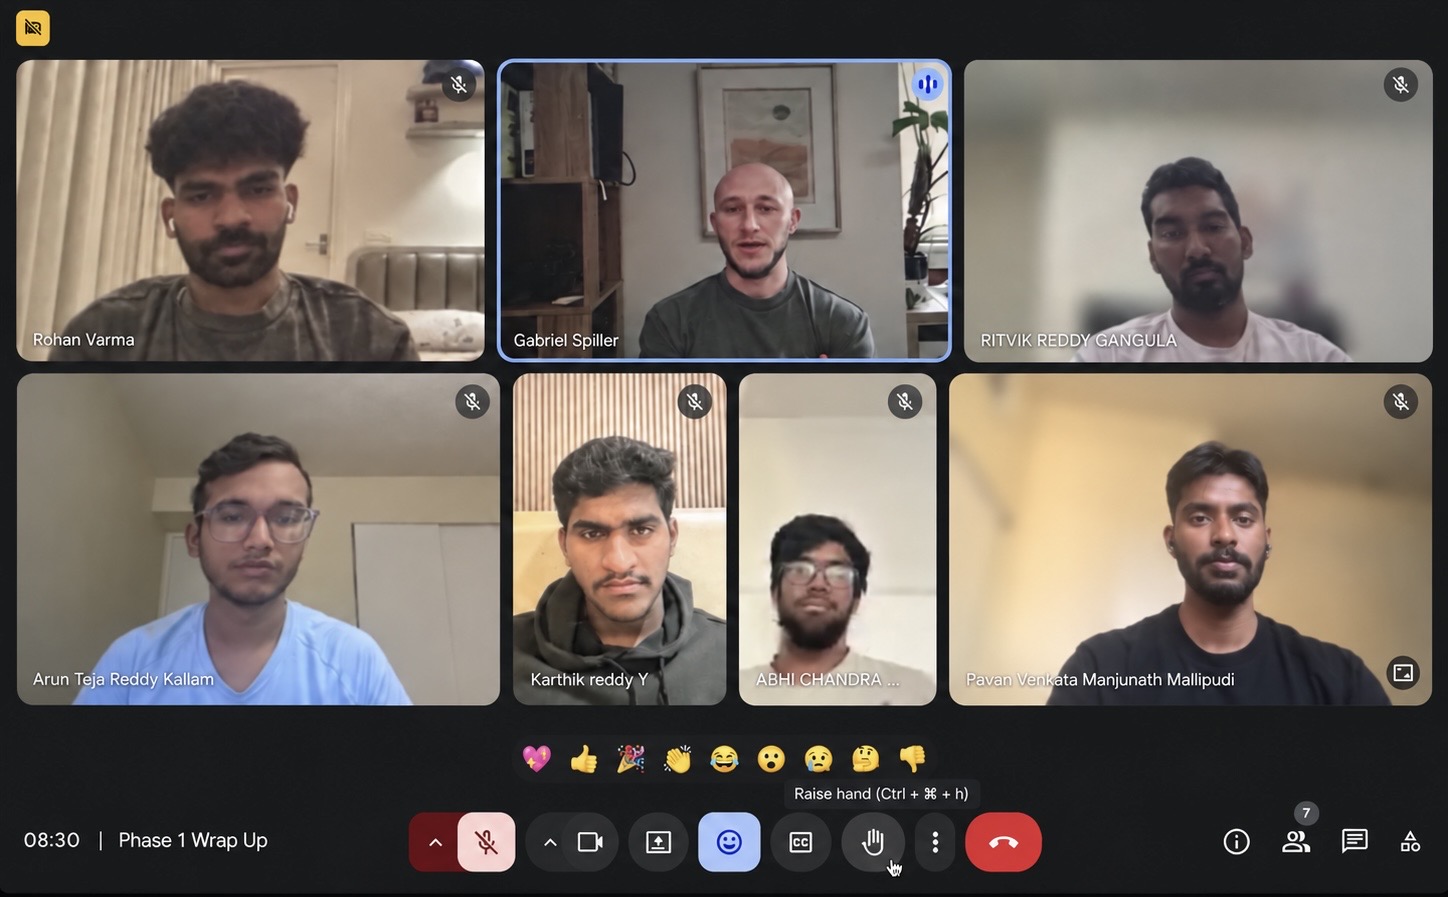
Remote working session with the Food Forest AI team
Weekly working session · Food Forest AI

Selected Work

2024 - 2026 / Index

Subscription Churn Analytics 01

Subscription Churn Analytics

Data Analytics & BI · Data Engineering · Data Science & ML

Churn across 23M KKBox billing transactions and 410M member-days. Manual renewers churn at 20.9% against 2.8% on auto-renew, and a gradient-boosting model scores 0.944 AUC on held-out 2017 decisions, its top risk decile capturing 82% of churners against 68% for a rules baseline. dbt and DuckDB behind a Next.js dashboard.
dbtDuckDBChurn Analytics
↗
Credit Decisioning Engine 02

Credit Decisioning Engine

Data Science & ML · Data Analytics & BI

Approve or decline, scored on profit and fairness rather than accuracy alone. XGBoost over 618,584 LendingClub loans with time-based validation; declining the riskiest 12% lifts 2015 profit by 13.8%. A fairness monitor reports who that costs.

XGBoostCredit RiskFairness
↗
RAG Document Assistant 03

RAG Document Assistant

AI Engineering · Software Engineering

Ask questions about your own PDFs and get answers traceable to the exact chunk. Runs fully local: MiniLM embeddings, Chroma, and Qwen2.5-1.5B behind FastAPI. Retrieval takes the benchmark set from 1/8 to 6/8 correct.

RAGFastAPIVector Search
↗
SmartBudget 04

SmartBudget

Software Engineering · Data Engineering · AI Engineering

Double-entry bookkeeping for freelancers. Bank CSV import with duplicate detection, rules-then-LLM categorization, invoices and AR aging, and statements built straight from the ledger. FastAPI, PostgreSQL and React, multi-tenant, 153 backend tests.

FastAPIPostgreSQLReact
↗
Plant Disease Classifier 05

Plant Disease Classifier

Data Science & ML

Identifies 38 leaf diseases across 14 crops from a single photo. EfficientNet-B0 transfer learning on PlantVillage, 98.21% test accuracy from a 4.06M-parameter model, served through a Streamlit app that flags low confidence.

PyTorchDeep LearningComputer Vision
↗
ReadmitScope US 06

ReadmitScope US

Data Analytics & BI · Data Science & ML

CMS Medicare readmissions end to end: live ingestion, cleaning and QA, statistical testing, and ownership and star-rating enrichment, in a deployed React dashboard for exploring excess readmission patterns.

PythonHealthcareReact
↗
CardioScope 3D 07

CardioScope 3D

Data Science & ML · Data Analytics & BI

297 real patients as an orbitable 3D point cloud, with PCA, k-means clustering, and a logistic-regression risk model at ROC-AUC 0.906 under stratified 10-fold cross-validation.

Three.jsReactML
↗
Enterprise Data Lakehouse Integration Platform 08

Enterprise Data Lakehouse Integration Platform

Data Engineering · Data Analytics & BI

A Databricks lakehouse in Bronze, Silver and Gold layers. PySpark and Delta Lake MERGE for incremental loads, schema harmonization and data-quality validation from S3, governed by Unity Catalog.

DatabricksPySparkDelta Lake
↗

Skills

What I work with

Languages

PythonSQLRBash

Data Engineering

PostgreSQLMySQLSQLAlchemyPySparkETL / ELTData ModelingDimensional ModelingData WarehousingDelta Lakedbt

Machine Learning & Deep Learning

PyTorchTorchvisionscikit-learnTransfer LearningCNNsComputer VisionImage ClassificationModel EvaluationWeights & BiasesPCA / ClusteringRegression

Cloud & Platforms

AWSAWS S3Amazon BedrockAmazon SageMakerDatabricksSnowflakeAirflowDockerGit / GitHubLinux

Data & BI

PandasNumPySciPyExcelPower BITableauTableau PrepStreamlitPlotlyMatplotlibD3.jsJupyter

Data Analytics

EDAStatistical AnalysisA/B TestingCohort AnalysisKPI ReportingAd-hoc AnalysisRoot Cause AnalysisHypothesis TestingStakeholder Management

GenAI & AI Tooling

Claude CodeOpenAI CodexCursorGitHub CopilotAntigravityLovableAnthropic Claude APILangChainHugging FacePrompt EngineeringRAGVector SearchFastAPIResponsible AI

Certifications

AWS certified / verified credentials

Beyond the Data

Off the clock
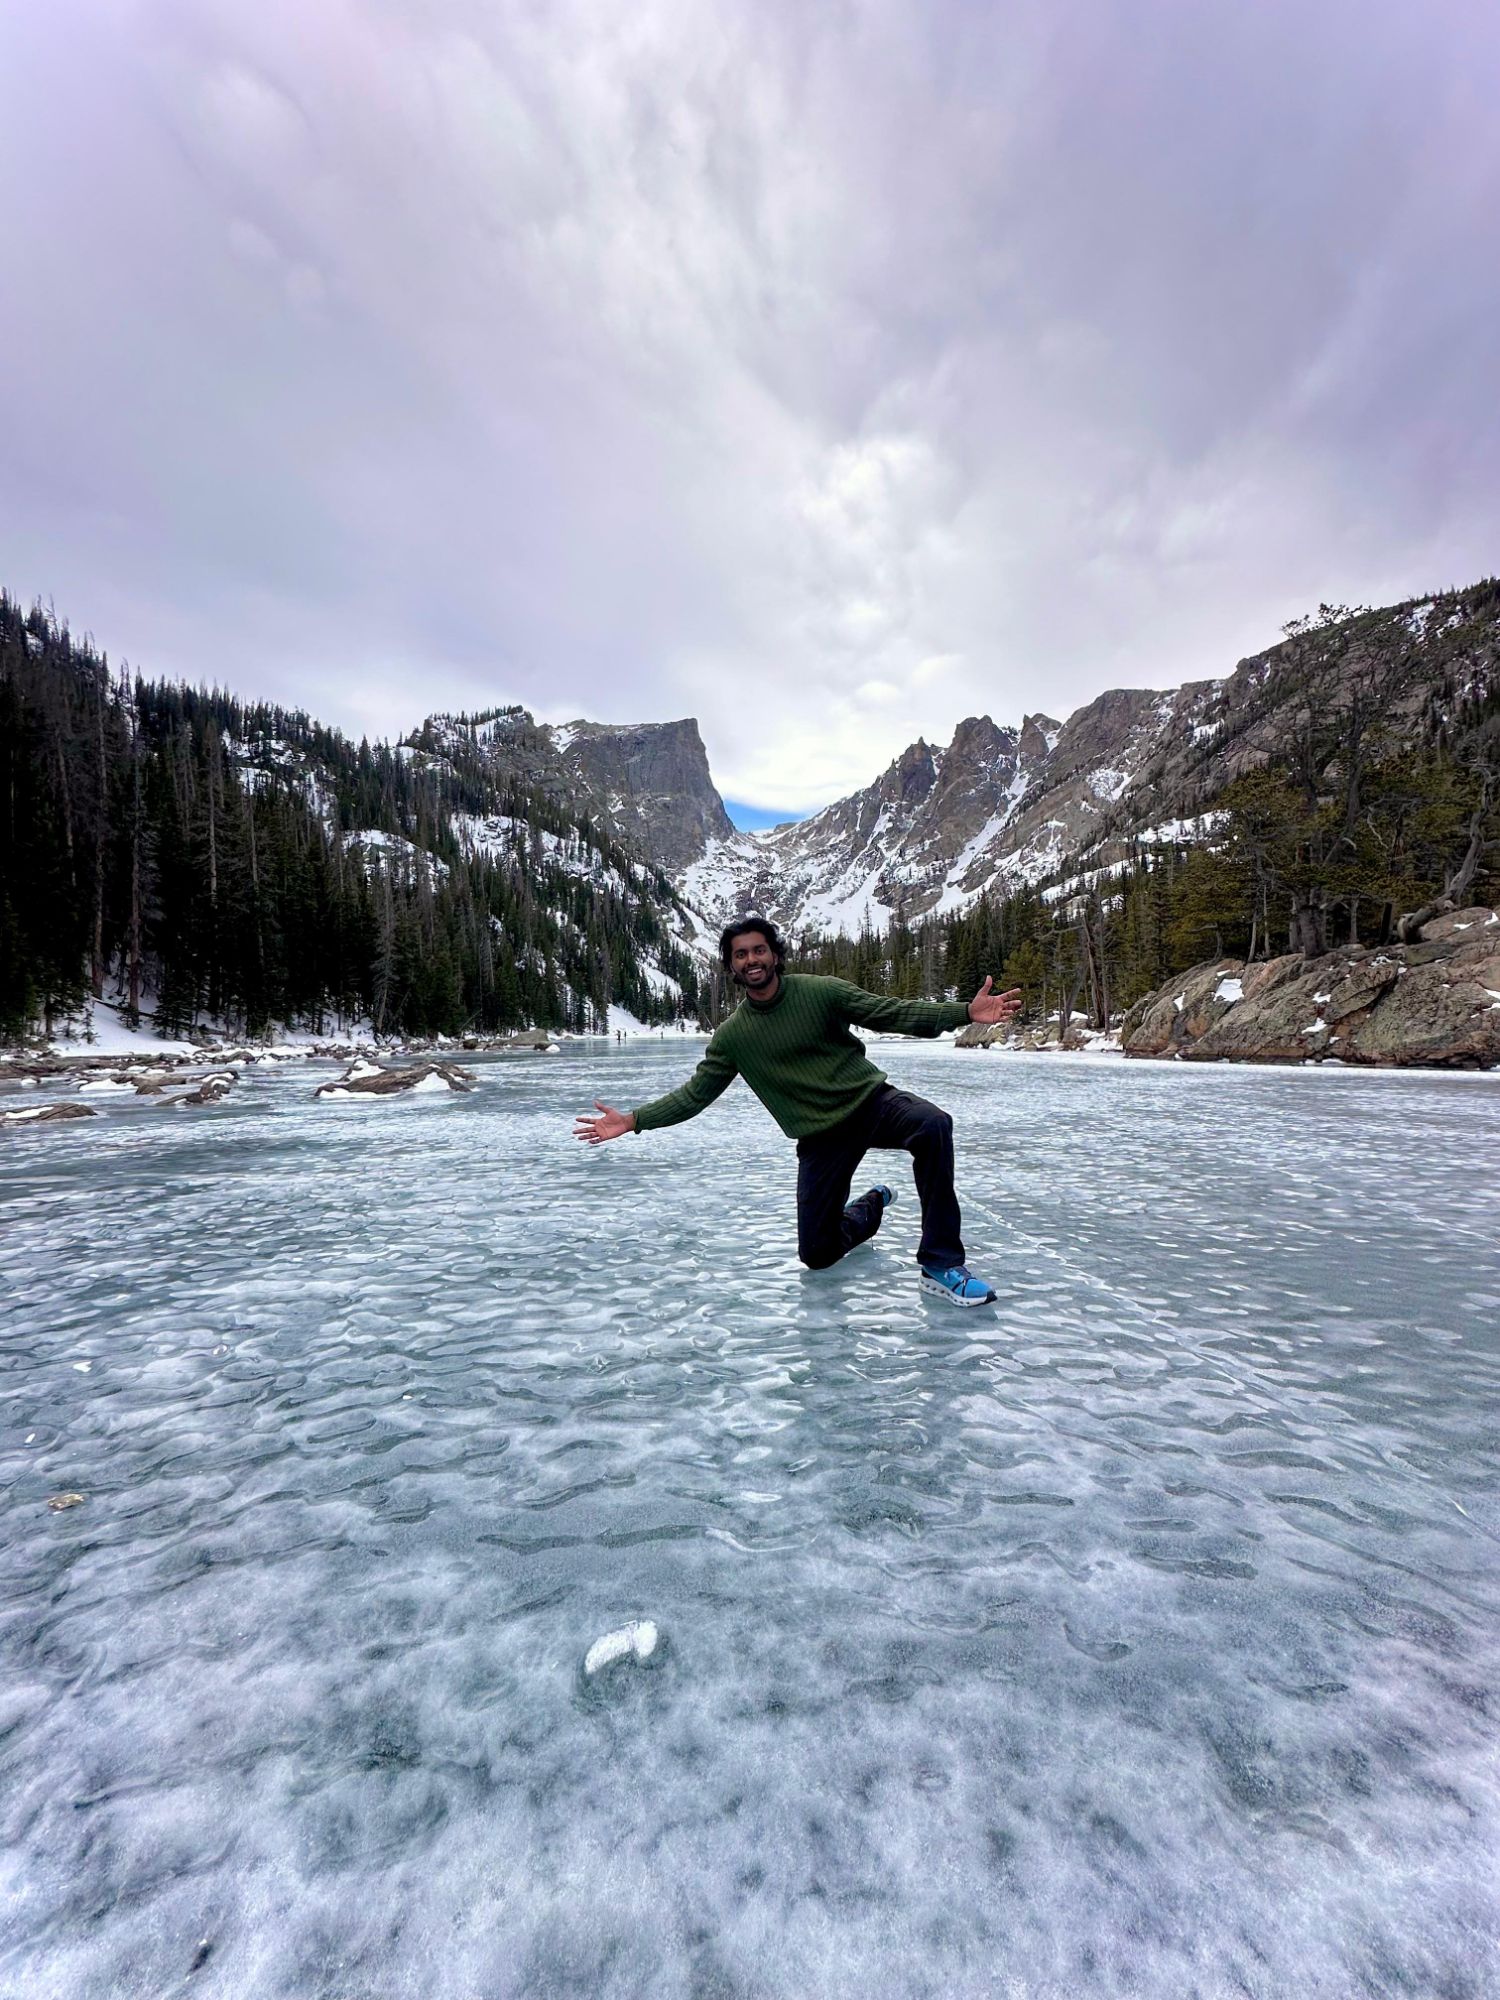
Pavan standing on a frozen alpine lake in Rocky Mountain National Park, Colorado
Rocky Mountain National Park · Colorado

When I'm not in a query editor, I'm usually somewhere with worse signal and a better view.

I travel whenever I get the chance, and the trips I like most are the ones that involve a trailhead: national parks, long climbs, and the kind of cold that makes you check the forecast twice. Same instinct as the work, really: pick a hard problem, break it into switchbacks, keep moving.

12,633 ft Fun factI've hiked Humphreys Peak, the highest point in Arizona.
TravelHikingNational ParksAdventure SportsPhotography

Resume

One page, the whole story

Pavan Venkata Manjunath Mallipudi

B.S. Computer Science · Data Science minor · Magna Cum Laude · Arizona State University, May 2026. Open to data analyst, data engineer, data scientist, and AI / ML engineer roles.

✔  OPT approved · 3-year STEM OPT
  • B.S. Computer Science + Data Science minor · Magna Cum Laude (May 2026)
  • Data analytics, data engineering, and ETL across three roles
  • Deployed analytics & lakehouse projects (PostgreSQL, Databricks, Streamlit)
  • AI and ML projects: RAG retrieval, deep learning, and LLM-backed services
  • Python · SQL · R · Spark · PyTorch · Power BI · Tableau · dbt
  • 5× Dean's List · GPA 3.76 / 4.0
  • AWS Certified AI Practitioner · AWS Certified Cloud Practitioner
  • IBM Data Analyst Professional Certificate
Open to data and AI roles
Start a conversation

pvmmallipudi@gmail.com · Tempe, Arizona